Stop Guessing, Start Scraping: The Engineering Mandate for AI Search Synthesis
The industry is currently suffocating under a deluge of theoretical think-pieces about Generative Engine Optimization (GEO). Marketers are debating how to “rank” in ChatGPT, Perplexity, and Google’s AI Overviews, yet they are attempting to solve a 2026 data engineering problem using 2015 marketing tools.
You cannot optimize what you cannot measure. Staring at a third-party SaaS dashboard designed to track traditional search engine results pages (SERPs) will tell you nothing about how a Large Language Model (LLM) parses, weights, and synthesizes your digital architecture. To understand how AI engines view your brand, technical teams must stop guessing and start interrogating the models directly.
Here is the blueprint for moving GEO out of the marketing department and into your engineering pipeline.
The Death of the Standard Crawler
Traditional SEO tools rely on basic crawler emulation. They fetch your HTML, parse the DOM, and measure keyword density, backlink velocity, and basic indexability. This was highly effective when search engines functioned as basic retrieval systems mapping keywords to documents.
AI search engines do not merely retrieve; they synthesize and resolve entities. When a user asks Perplexity to “compare enterprise cloud security vendors in Cape Town,” the engine isn’t looking for the page with the highest keyword density for that exact phrase. It is executing a semantic query against its vectorized index to extract verifiable entities, trust signals, and structured relationships. Standard rank trackers cannot emulate this. If you want to know if an LLM understands your site’s architecture, you have to feed your raw payload into an LLM and parse the output.
The Python Diagnostic Framework
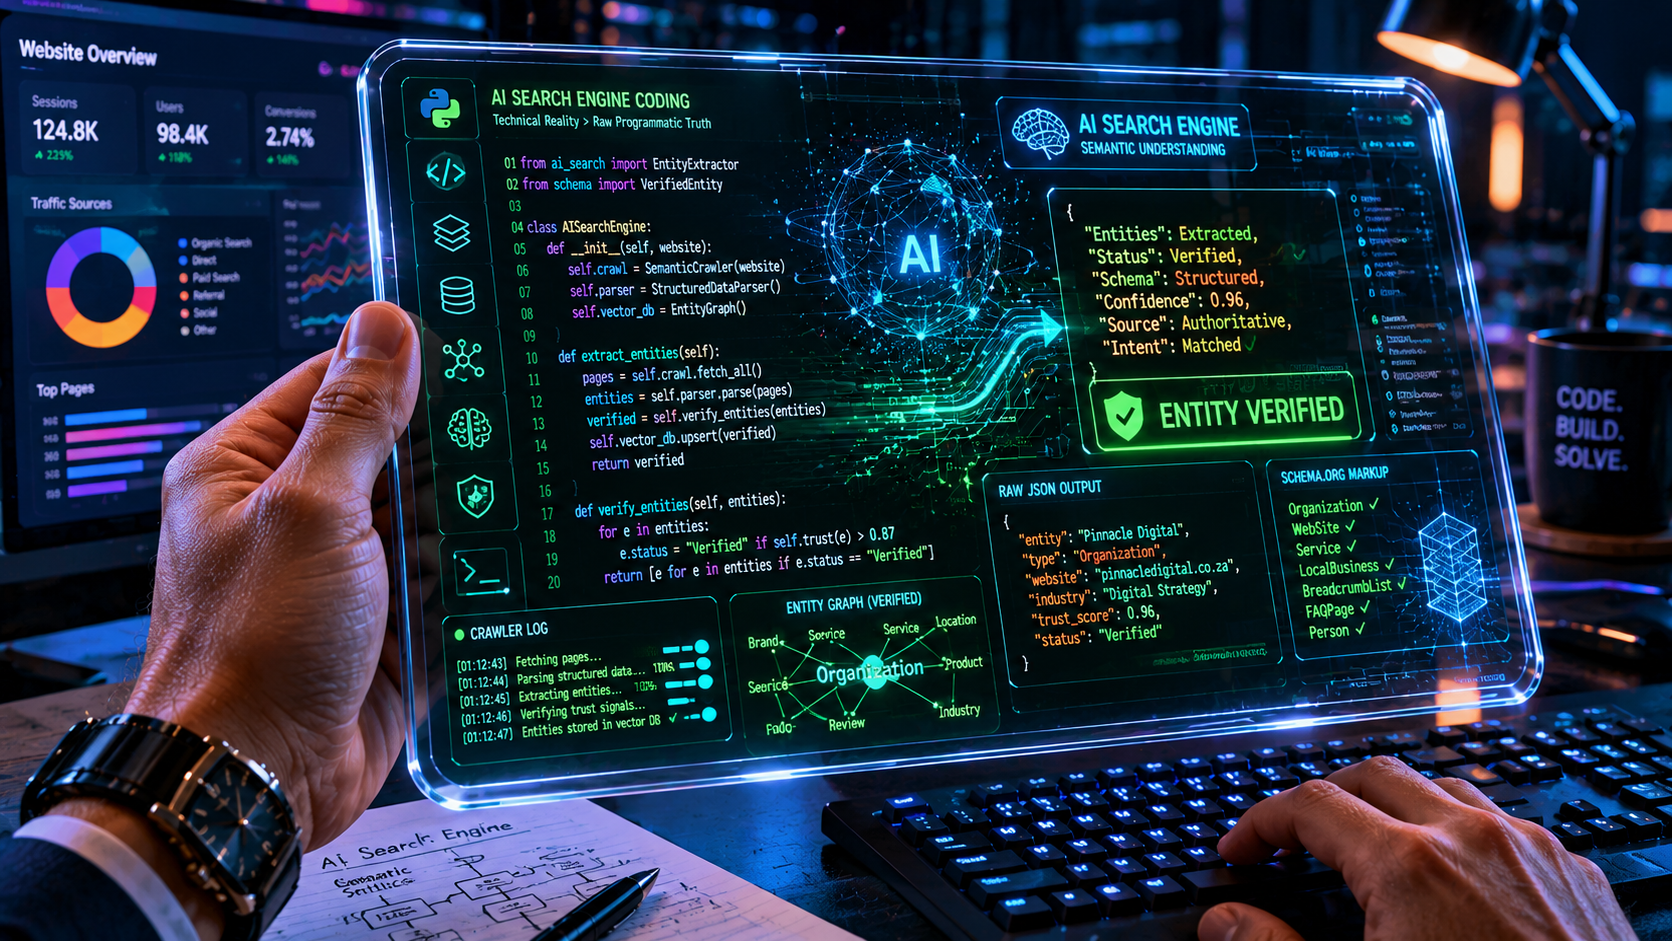
To empirically audit your AI search visibility, your engineering team needs to build a custom diagnostic pipeline. The objective is to scrape a target URL on your domain, strip the noise, and force an LLM (via API) to output exactly what it believes your core entities, services, and trust signals are.
This requires a straightforward stack:
- requests for the initial HTTP payload retrieval.
- BeautifulSoup (or lxml) to strip the DOM down to its core semantic text and JSON-LD nodes.
- google-generativeai (or the OpenAI/Anthropic SDKs) to query the model programmatically.
Writing the Interrogation Script
Below is an illustrative Python script that fetches a specific URL, cleans the payload, and interrogates the Gemini API to see how the model parses the page’s entity structure.
Python
import requests
from bs4 import BeautifulSoup
import google.generativeai as genai
import json
# Configure your API Key
genai.configure(api_key=”YOUR_GEMINI_API_KEY”)
def fetch_and_clean_dom(url):
headers = {‘User-Agent’: ‘Mozilla/5.0 (Windows NT 10.0; Win64; x64)’}
response = requests.get(url, headers=headers)
soup = BeautifulSoup(response.text, ‘html.parser’)
# Strip unnecessary scripts and styles to save token space
for element in soup([“script”, “style”, “nav”, “footer”]):
element.extract()
return soup.get_text(separator=’ ‘, strip=True)
def audit_entity_extraction(text_payload):
model = genai.GenerativeModel(‘gemini-1.5-pro’)
prompt = f”””
You are an AI Search Engine crawler. Analyze the following webpage payload.
Extract the core entities, primary services offered, key personnel, and any explicit trust signals (e.g., licenses, physical addresses, partnerships).
Return the response STRICTLY as a JSON object with the following keys:
“primary_entities”, “services”, “key_personnel”, “trust_signals”, “synthesis_confidence_score”.
Webpage Payload:
{text_payload[:8000]} # Truncating for token limits if necessary
“””
response = model.generate_content(prompt)
return response.text
# Execute the diagnostic
target_url = “https://your-enterprise-domain.com/services/m-and-a-advisory”
clean_text = fetch_and_clean_dom(target_url)
synthesis_result = audit_entity_extraction(clean_text)
print(json.dumps(json.loads(synthesis_result), indent=4))
Analyzing the Synthesis Gap
When you run this script across your core service pages, you are looking for the synthesis gap—the delta between what your business actually does and what the LLM thinks you do based on your digital infrastructure.
If the output JSON returns missing key personnel, hallucinates a service you don’t offer, or returns a low synthesis_confidence_score, you have a critical architectural failure. This means your unstructured on-page text and your semantic HTML are ambiguous.
When an LLM struggles to parse your page in this controlled, direct-prompt environment, it will absolutely fail to synthesize your brand in a live, zero-click search environment where it is comparing you against highly optimized competitors. A failure here proves that your site requires rigorous JSON-LD injection and entity-relationship mapping to explicitly define the data the model is currently failing to extract.
The Engineering Mandate
Modern search visibility is no longer a content marketing task; it is a data engineering mandate. Your website is no longer just a visual interface for human users—it is an API endpoint for non-human agents.
If your technical teams are not actively deploying scripts to test LLM synthesis, you are operating entirely in the dark. Stop relying on commoditized third-party tools to tell you how AI engines read your site. Write the code, extract the payload, and audit your digital architecture with the exact technology that is disrupting your market share.